Low-resource language learning
Better translation through word sense disambiguation
Can unsupervised word senses improve translation without parallel training corpora?
Journal article · IETE Journal of Research · 2023 · Co-author
Published journal article: IETE Journal of Research, 69(12), 8848–8858 (2023); published online July 22, 2022.
My contribution. As an undergraduate research assistant at NIT Hamirpur, I developed the unsupervised word-sense-disambiguation pipeline and integrated it into the statistical translation workflow. I co-authored the journal article.
01 / THE QUESTION
Background.
A translation system can select a plausible word with the wrong meaning when source words are polysemous or homonymous. This is especially difficult when parallel data and sense-labeled resources are limited.
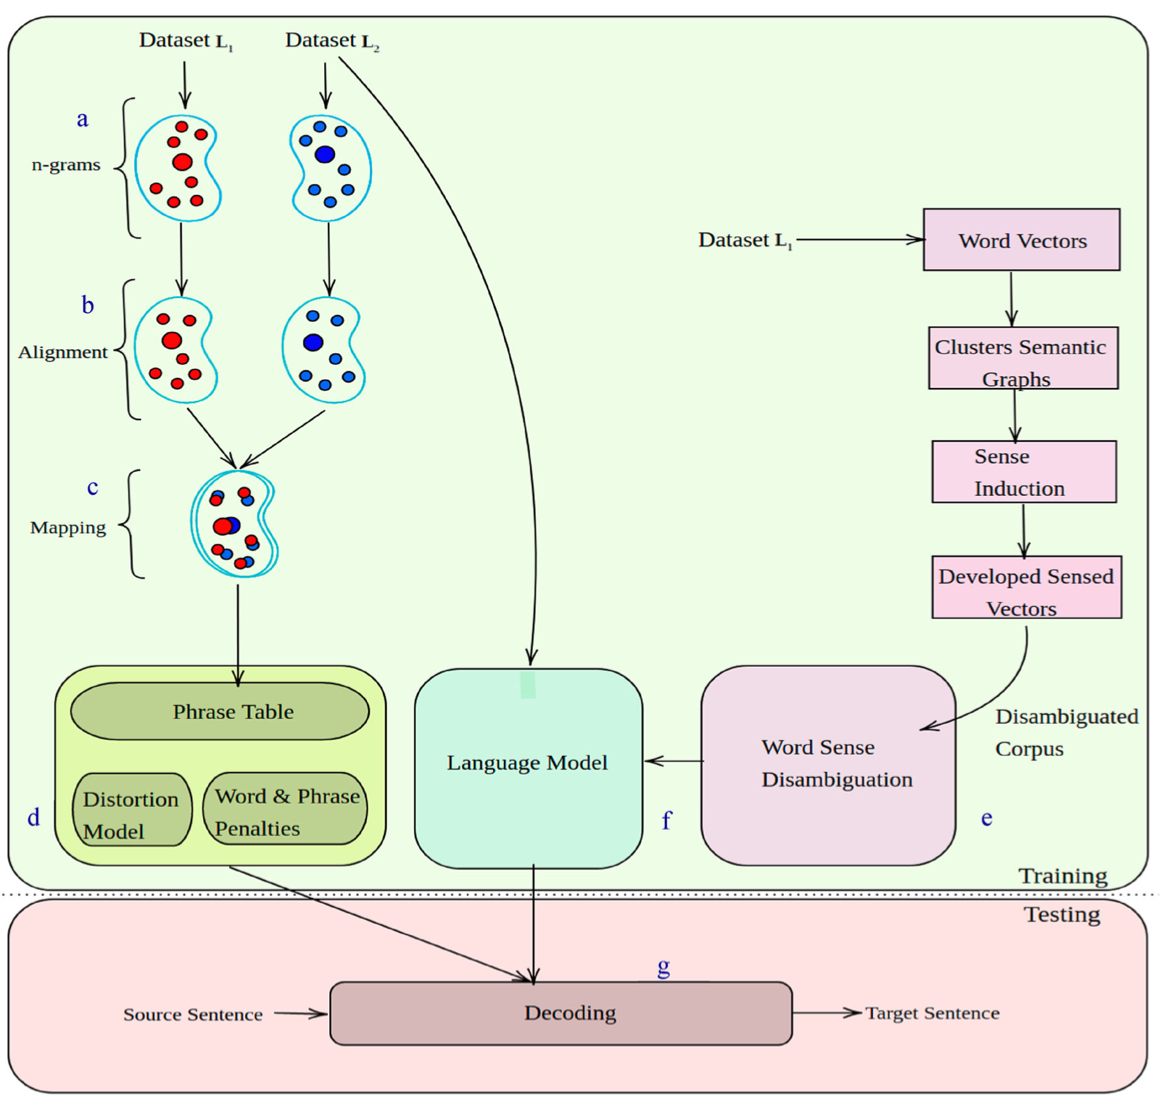
The study introduces unsupervised word sense disambiguation into an unsupervised statistical machine translation pipeline. Instead of relying on a manually built sense inventory, it induces senses from monolingual word embeddings and their neighborhood structure.
02 / THE APPROACH
Method, step by step.
Open a step to explore the approach.
01Build a cross-lingual translation space
Source and target monolingual corpora produce n-gram embeddings. VecMap aligns the spaces so a phrase table can be induced for the baseline unsupervised statistical translation system.
02Induce word senses
Cosine-similar neighbors form semantic graphs. Ego-network clustering with Chinese Whispers separates densely connected groups that represent different senses. Weighted combinations of cluster word vectors form sense vectors.
03Disambiguate the source corpus
The context of a source word is used to select its appropriate induced sense, producing a disambiguated source corpus for sense-aware language modeling and translation.
04Integrate into decoding
The sense-aware representation is combined with phrase-table and language-model scores in the Moses-based pipeline. Feature weights are tuned with minimum error rate training, with iterative back-translation used to improve the translation system.
Study design
Five English-to-Indic directions: Hindi, Kangri, Tamil, Telugu, and Bengali. The study uses monolingual training corpora, a Monoses/Moses baseline, 5-gram language models, and BLEU and METEOR for evaluation. “Kn” denotes Kangri in this paper.
03 / THE EVIDENCE
Results.
Adding WSD improved BLEU and METEOR in all five translation directions. Compare the baseline and WSD scores below, or use the bars to see the gain in metric points.
Translation quality: BLEU
Higher is better. Absolute gains are calculated from the printed scores in Table 3 and rounded to two decimal places.
BLEU gain over baseline · points
0 3
| Direction | Baseline | Baseline + WSD | Gain |
|---|---|---|---|
| English → Hindi | 19.8 | 22.1 | +2.30 |
| English → Kangri | 12.22 | 14.9 | +2.68 |
| English → Tamil | 14.98 | 15.76 | +0.78 |
| English → Telugu | 11.629 | 13.944 | +2.32 |
| English → Bengali | 10.768 | 12.554 | +1.79 |
Translation quality: METEOR
Higher is better. Absolute gains are calculated from the printed scores in Table 4.
METEOR gain over baseline · points
0 1.5
| Direction | Baseline | Baseline + WSD | Gain |
|---|---|---|---|
| English → Hindi | 3.32 | 4.398 | +1.078 |
| English → Kangri | 1.031 | 2.374 | +1.343 |
| English → Tamil | 6.069 | 6.789 | +0.720 |
| English → Telugu | 7.695 | 8.388 | +0.693 |
| English → Bengali | 3.045 | 4.236 | +1.191 |
Numerical results: Saxena et al., IETE Journal of Research, Tables 3 and 4. Kangri BLEU gain is 2.68 points; Hindi gain is 2.30 points.
04 / WHAT IT MEANS
Conclusions.
- Explicitly modeling word senses can improve lexical choices even when both translation and sense induction rely on monolingual data.
- The gains across five language directions support sense-aware decoding as a useful addition to the evaluated statistical translation baseline.
Limitations & next steps
We evaluated against an unsupervised statistical machine translation baseline on five English-to-Indic test sets. Comparisons with neural translation systems and large language models remain future work.
05 / READ FURTHER
Citation & sources.
Improved Unsupervised Statistical Machine Translation via Unsupervised Word Sense Disambiguation for a Low-Resource and Indic Languages
IETE Journal of Research · 69(12):8848–8858 · Online first: July 2022
Citation
Saxena S, Chaurasia U, Bansal N, Daniel P. Improved Unsupervised Statistical Machine Translation via Unsupervised Word Sense Disambiguation for a Low-Resource and Indic Languages. IETE Journal of Research. 2023;69(12):8848–8858. https://doi.org/10.1080/03772063.2022.2098189
Published journal article: IETE Journal of Research, 69(12), 8848–8858 (2023); published online July 22, 2022.